

Developer guide: building market analysis research agents with examples
Three market analysis agents compared against built-in LLM web search, with code and example runs.


Nimble's Expert
Developer guide: building market analysis research agents with examples
Three market analysis agents compared against built-in LLM web search, with code and example runs.
Nimble's Expert


Most popular articles
Get structured, reliable data for your stack.
Intro
Market analysis depends on evidence that rarely shows up in a search results page: a vendor's actual plan tiers, what customers are really complaining about right now, or every company competing in a category you are trying to size. Pricing and packaging pages render client-side and paginate, review platforms sit behind anti-bot protection, and the long tail of a market never makes an analyst's list.
Built-in LLM web search handles the easy version of these questions (a headline, a company overview, a well-covered funding round), but it will not hold up when the evidence has to be normalized, counted, or reconciled. Nimble's Web Search Agents go deeper into the specific pages a market question depends on, so you can build agents that retrieve and use that context directly.
This post walks through three market analysis use cases. For each, we send the same research question to GPT-5.1's built-in web search tool and to a Nimble Web Search Agent (you hand Nimble a research objective and it runs the workflow itself), compare what came back, and then show how a LangChain agent puts the Agent API's output to work.
You can create a free Nimble account here.
Key takeaways
- Given the identical research question, GPT-5.1's built-in web search consistently under-delivered against Nimble's Agent API: fewer pages actually read, numbers it found but declined to report, and in one case an admission that it was giving up early and pointing to someone else's list instead of finishing the research.
- The Agent API runs the full workflow: planning, searching, site navigation, cross-checking, synthesis, schema-shaped output, and confidence scoring.
- Web Search Agents learn a recurring use case across runs, retrieving progressively deeper context at lower cost, which matters here because market tracking is usually recurring work.
- In each use case below, the retrieval and extraction happen through Nimble; the arithmetic, the statistical rules, and the verification logic stay in your code. That split is what makes the numbers defensible.
Getting started with Nimble:
- Testing: give your coding agent this URL to onboard it to Nimble
- Production: integrate Nimble into your stack through our MCP server or integrations
Use Case 1: Competitive Pricing and Packaging Comparison
Use case + agent overview
Product, strategy, and competitive intelligence teams need to know how competitors price and package, and what a given customer profile would actually pay across them. The evidence lives on pricing pages, plan tables, and changelogs that are often client-side, paginated, or too low-traffic to surface in search, and vendors price in different units (per host, per GB, per seat), so the published numbers can't be compared as they stand.
We built a pricing-comparison-agent, a LangChain agent that:
- Accepts a set of competitors and a buyer profile (for example: 200 hosts and 2,000 GB of ingest per month), and retrieves each vendor's pricing, tiers, usage limits, and packaging into a structured record with a source URL per value.
- Normalizes the different pricing units and computes a modeled annual cost for the buyer profile, showing its assumptions, or routes the vendor to "quote required" with the specific missing input if the cost can't be computed from public pages.
- Reads the changelog for packaging changes announced in the last 90 days, dated from the source.
- Writes the comparison table, cost ranking, and quote-required list, plus a live dashboard it opens in the browser once the run finishes.
Full agent (code + example run): github.com/Nimbleway/cookbook/tree/main/apps/pricing-comparison-agent
Comparison: GPT-5.1's built-in web search vs the Agent API
Both were asked the identical research question:
"Research how Datadog, New Relic, and Grafana Labs currently price and package their product. For each, return plan tiers, list prices with their billing unit, included usage allowances, overage rates, and any packaging change announced in the last 90 days with its date. Cite the page each value came from, and mark any value not published publicly as unavailable rather than estimating it."
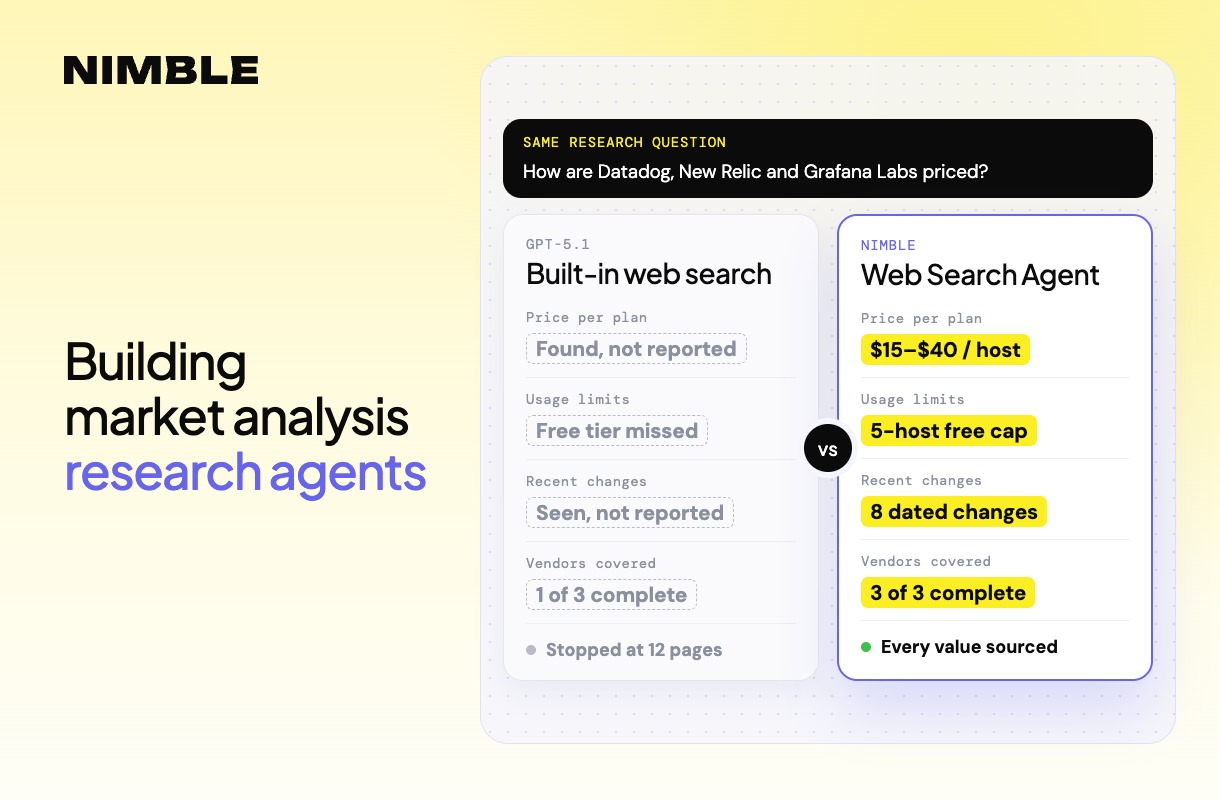
GPT-5.1's built-in web search made 2 search calls, read 12 distinct pages, and came back cautious to the point of being unusable. It found Datadog's real per-host prices, but declined to report them:
"Per-host list prices for Infrastructure and APM: Unavailable (not published in Datadog docs or pricing text I can see). Multiple third-party sources quote $15/host/month (Infra Pro), $23/host/month (Infra Enterprise)... but these are explicitly framed as derived from Datadog's pricing page... and are not Datadog-owned domains, so I'm treating the numeric values as out of scope."
Those numbers are correct; our Agent API run confirms both independently, but the built-in search tool had them in hand and chose not to report them. It never surfaced Datadog's free Infrastructure tier or its 5-host cap at all. On packaging changes, it found a real signal and did the same thing:
"A third-party tracker notes that around September 11-12, 2026, it detected [pricing changes]... since your instructions ask for values published publicly by the vendor, I cannot treat those dollar figures as authoritative."
Its final answer for two of the three vendors was mostly a table of "Unavailable," with a closing section suggesting the reader open the pricing pages in a browser and paste the numbers in manually.
Nimble's Agent API:
run = nimble.agents.run(
    input=(
        "Research how Datadog, New Relic, and Grafana Labs currently price and package "
        "their product. For each, return plan tiers, list prices with their billing "
        "unit, included usage allowances, overage rates, and any packaging change "
        "announced in the last 90 days with its date. Cite the page each value came "
        "from, and mark any value not published publicly as unavailable rather than "
        "estimating it."
    ),
    use_case="research",
    effort="high",
    output_schema=PRICING_SCHEMA,
)
Parameters used:
use_case="research", a bounded set of known vendors researched in depth, not an open-ended discovery task.effort="high", because the answer requires navigating into pricing and documentation pages across three separate vendor sites, not reading search snippets.output_schema=PRICING_SCHEMAwith an explicittier_typeandbilling_unitfield per price, so every value comes back normalizable rather than as prose.- The instruction to mark unpublished values as unavailable is carried in the prompt, so the model reports an honest gap instead of a plausible-sounding number.
On the same question, the Agent API returned real prices for every vendor: 8 priced tiers for Datadog (Infrastructure Free capped at 5 hosts, Infrastructure Pro at $15/host, Infrastructure Enterprise at $23/host, DevSecOps and APM tiers up to $40/host), 4 for New Relic ($0.40/GB and $0.60/GB overage beyond the 100 GB free allowance, by edition), and 3 for Grafana Labs. It also surfaced 4 dated packaging changes for Datadog (a Log Management ingest price cut from $0.10 to $0.0833/GB on 2026-08-01, a new AI Credits line at $1.30/credit on 2026-08-03, among others) and 4 for New Relic, each with its own date and source page, the exact class of finding the built-in search tool found and then declined to report.
What the Agent API captured that built-in search didn't.
The gap wasn't about whether the information existed online; in both cases it did. It was that built-in search, reading a handful of top-ranked pages in one or two passes, couldn't distinguish a vendor's own authoritative page from a third-party aggregator closely enough to commit to a number, and had no mechanism to keep digging into changelog and billing-doc pages the way a multi-step research workflow does. The Agent API's deeper per-vendor navigation is what turned "unavailable" into an exact, sourced number.
What the agent does with it.
The pricing-comparison-agent parses the Agent API's output into a structured tier list (tier_name, billing_unit, an explicit tier_type, and the rate fields that apply to that type), normalizes the units, and runs the cost model against the buyer profile. On a real 200-host, 2,000 GB/month buyer, Datadog's Infrastructure Pro tier priced at $36,000/yr, New Relic's free/usage tier came back cheaper at $9,120/yr, and Grafana Labs was correctly routed to quote required since its usage-based tiers aren't published with enough detail to price them.
One extraction detail worth showing: Datadog's free Infrastructure tier is capped at 5 hosts. An early version of the cost model treated any flat-fee tier as unconditionally free and priced it at $0/yr for all 200 hosts, before the buyer profile was checked against the tier's actual cap. The fix was to carry the cap through extraction (included_quantity on a flat tier means "this is the ceiling it applies to," not just "included units before overage") and have the cost model treat a tier the buyer's quantity exceeds as inapplicable, not free.
Run this on a schedule, and the agent learns which vendor paths carry real pricing changes, so later runs reach the same depth with fewer searches.
Use Case 2: Consumer Sentiment Analysis
Use case + agent overview
Brand, product, and insights teams need to know what customers actually say about a specific brand, which complaints are growing, and how sentiment shifted after a price change, a menu change, or an operational problem. That evidence is spread across review platforms, community threads, and news coverage. Almost none of it is reachable through a single query: review sections load client-side and paginate, community threads rank poorly against brand-owned pages, and most platforms sit behind anti-bot protection.
The analytical risk is as important as the retrieval problem. Review and forum data is a convenience sample, so the agent has to report volume and sources rather than present a sentiment percentage as a market-representative statistic.
We built a brand-sentiment-agent, a LangChain agent that:
- Accepts a brand and a comparison window (default: the last 90 days against the 90 days before that).
- Retrieves reviews, ratings, and discussion across review platforms, community threads, and news coverage.
- Extracts a structured record per item: source, date, star rating where present, theme, and sentiment label.
- Applies a minimum sample size per theme and drops anything below it into an "insufficient volume" bucket rather than reporting it as a finding.
- Compares each theme against the prior window and computes the change in negative volume.
- Writes a ranked triage list of themes that crossed the escalation threshold, each with volume, direction, sample size, source mix, and representative sourced quotes, plus a full theme table and a live dashboard it opens in the browser.
Full agent (code + example run): github.com/Nimbleway/cookbook/tree/main/apps/brand-sentiment-agent
Comparison: GPT-5.1's built-in web search vs the Agent API
Both were asked the identical research question:
"Find and classify customer sentiment toward Chipotle over the last 180 days, covering review platforms, community discussion, and news coverage of any price or product changes. State the sample size and source mix behind each theme, and cite the source and date for every item."
GPT-5.1's built-in web search made a single search call, read 19 distinct pages, and wrote a genuinely fluent five-theme narrative summary, complete with dated citations. On its own terms, it reads well. But look at what it actually delivered against "state the sample size... for every item": every count in the response is a hedge, not a number: "~30-40 detailed reviews," "10-15 news/press and community posts," "2-3 industry and business press overviews." There is no per-item record: no individual date, source, and sentiment label for each piece of evidence, and no split between a current and a prior window at all; it narrates "the last 180 days" as one undifferentiated block.
Nimble's Agent API:
run = nimble.agents.run(
    input=(
        "Find and classify customer sentiment toward Chipotle over the last 180 days, "
        "covering review platforms, community discussion, and news coverage of any "
        "price or product changes. State the sample size and source mix behind each "
        "theme, and cite the source and date for every item."
    ),
    use_case="research",
    effort="high",
    output_schema=SENTIMENT_SCHEMA,
)
Parameters used:
use_case="research", since the objective is analysis of one subject across many sources, not building a list of entities.effort="high", because the themes only emerge after navigating into paginated review sections and long threads across several platforms.output_schema=SENTIMENT_SCHEMAwith a requiredsource,date,text_excerpt,theme, andsentimentfield on every single item, not a per-theme approximation. Requiring an exact record per item is what makes the output usable by code at all.
On the same question, the Agent API returned individually dated, sourced items, exact enough for our own deterministic pipeline to dedupe them, split them into a real current-vs-prior window, and compute an escalation percentage. On a real run, one theme, "Portions, Value & Pricing," escalated: 6 negative items in the current 90-day window against 3 the window before, a +100% rise, backed by sourced quotes with exact dates and URLs. Five other themes stayed below the minimum sample size and were correctly held back rather than reported as thin findings.
What the Agent API captured that built-in search didn't.
Built-in search's narrative is genuinely readable, but it's the output of a single pass over a batch of search results, summarized in prose. It cannot be dedup'd, windowed, or thresholded by downstream code, because it was never structured that way to begin with: "~30-40 reviews" is a sentence, not thirty-to-forty individually-checkable records. The escalation percentage this use case is built around, current-window volume compared exactly against the prior window, simply cannot be computed from a narrative that never separates the two periods.
What the agent does with it.
The same dedupe, current-vs-prior window split, minimum sample cutoff, and escalation math run downstream regardless of retrieval source; the Agent API's item-level output is what makes that math possible at all.
Use Case 3: Market Sizing and Category Landscape Mapping
Use case + agent overview
Sizing a category and mapping who is in it are the same job done in two directions. Top-down, published estimates sit behind paywalls or in press releases and rarely agree with each other. Bottom-up, you have to find every vendor in the category and describe each one consistently, which no single query returns and no analyst list covers in the long tail. The fields a team actually wants, deployment model, pricing model, target segment, funding, live on individual vendor sites in different formats.
We built a market-landscape-agent, a LangChain agent that:
- Accepts a category definition and explicit inclusion criteria.
- Discovers candidate vendors through several angled searches, then researches each one for the same field set.
- Issues an include or exclude ruling on every candidate with the criterion it failed, deduplicates, and ranks the included set.
- Collects published size and growth estimates with their source and methodology.
- Computes a bottom-up estimate from the mapped set, compares it against the published top-down estimates, and flags the gap when the two disagree rather than averaging them.
- Writes the landscape table, the exclusions list, and the reconciliation as files, with a range and a confidence grade rather than a single number, plus a live dashboard plotting the bottom-up range against every published estimate on a log scale.
Full agent (code + example run): github.com/Nimbleway/cookbook/tree/main/apps/market-landscape-agent
Comparison: GPT-5.1's built-in web search vs the Agent API
Both were asked the identical research question:
"Find about 30 vendors in the category: LLM observability and evaluation platforms. Inclusion criteria: dedicated LLM observability or evaluation product, not a general-purpose APM vendor; self-serve or clearly documented deployment. For each, return headquarters, product focus, deployment model, pricing model, target segment, funding, major investors, and disclosed revenue/ARR if publicly stated, with supporting evidence. Deduplicate, rule every candidate include or exclude with a reason for each exclusion, and list near-misses. Separately, find published size or growth estimates for this category with their source and methodology."
This is the sharpest gap of the three. GPT-5.1's built-in web search made 2 search calls, read 34 distinct pages, and stopped at roughly 20 of the requested 30 vendors, saying so directly:
"Because of length, I'm not going to fabricate detail for another 10 platforms where the data is thin. Instead I'll show how others have enumerated 25-48 tools, and how you can mine those with your own criteria."
It then pointed to three other people's vendor-comparison articles rather than finishing the research itself. On market sizing, it found no real published estimate for this specific category and said so, then built one anyway from an unrelated figure:
"There isn't yet a universally accepted 'LLM observability' category line in Gartner/IDC... If you assume [a generic GenAI infrastructure forecast] and a 5-15% allocation to observability and evaluation, then you land in a rough ballpark of $2-5B global annual spend by 2028-2030... These are inferred from published ratios and generic GenAI market forecasts rather than explicit 'LLM observability' revenue reports."
Asked for a published estimate with its source and methodology, it manufactured one instead and labeled its own number a guess, an honest disclosure, but not the deliverable that was asked for.
Nimble's Agent API:
run = nimble.agents.run(
    input=(
        "Find about 30 vendors in the category: LLM observability and evaluation "
        "platforms. Inclusion criteria: dedicated LLM observability or evaluation "
        "product, not a general-purpose APM vendor; self-serve or clearly documented "
        "deployment. For each, return headquarters, product focus, deployment model, "
        "pricing model, target segment, funding, major investors, and disclosed "
        "revenue/ARR if publicly stated, with supporting evidence. Deduplicate, rule "
        "every candidate include or exclude with a reason for each exclusion, and "
        "list near-misses. Separately, find published size or growth estimates for "
        "this category with their source and methodology."
    ),
    use_case="dataset_building",
    effort="high",
    output_schema=LANDSCAPE_SCHEMA,
)
Parameters used:
use_case="dataset_building"rather thanresearch, because the output is a set of entities with a uniform field set; the one product decision that changes across the three use cases in this post: research for a bounded analytical question, dataset building for open-ended discovery.- A target count of 30 in the prompt, telling the agent how hard to push discovery rather than stopping once a comfortable set is found.
- The exclusion criterion stated directly in the prompt so near-misses come back with reasons attached rather than silently dropped.
output_schema=LANDSCAPE_SCHEMA, feeding the bottom-up calculation downstream.effort="high", because the long tail of the category only appears after several rounds of discovery and per-vendor investigation.
On the same question, the Agent API found 31 vendors, with exclusion reasoning sharp enough to track acquisitions correctly (Arize is now Dynatrace-owned, Galileo is now Cisco-owned, both treated as their own dedicated entities rather than folded into the acquirer's exclusion). For market sizing, it surfaced 8 real published estimates from named research firms (The Business Research Company, Precedence Research, DataIntelo, SNS Insider, NextMSC, and Globe Market Research), every one flagged as 9x to 112x the bottom-up midpoint, a real and citable disagreement, not an inferred number.
What the Agent API captured that built-in search didn't.
The built-in tool didn't fail quietly; it told the truth about its own limits (openly declining to fabricate detail, openly labeling its market-size figure a guess), which is honest but is not the same as doing the research. The Agent API's multi-round discovery kept going past the point where a single-pass search tool stopped, and its sizing pass found real analyst figures to reconcile against instead of manufacturing one from an unrelated forecast.
What the agent does with it.
Compute the bottom-up estimate, run the reconciliation against the published figures, and write the artifacts with the range and confidence grade. With 31 included vendors, the bottom-up estimate came to $330K to $249.4M (confidence: medium). Read individually, none of the 8 published estimates are measuring the same thing this agent mapped; most size "AI observability" or "AI model evaluation" broadly, not the specific set of dedicated LLM-observability vendors a buyer would actually shortlist. Eight analyst firms publishing eight different broad-category numbers, none of which line up with a bottom-up count of the actual dedicated vendors, is exactly the reconciliation problem this use case exists to make visible instead of averaging away.
Why Nimble Goes Deeper for Market Analysis
Specialized retrieval with self-learning research.
Generic search treats every query similarly. Nimble specializes retrieval around the use case and the information being sought, helping it identify better sources and retrieve the deeper context required to complete the task. Web Search Agents learn the use case across runs, including which sources and retrieval paths consistently produce useful information. Market tracking is usually recurring work, so this compounds: the vendor pages, directories, and outlets that reliably carry real changes become the paths the agent takes first.
Go beyond search results with intelligent site navigation.
Built-in LLM web search typically relies on sending a small number of search queries and reading the top results. Web Search Agents dive deeper into high-value websites by navigating into pages, not just reading what a search index surfaces. Pricing tables, plan limits, changelog history, and vendor-by-vendor discovery are the clearest examples in this post: pages that a one- or two-pass search tool reads a handful of times and then stops, where the Agent API kept going.
Reliable access to web data.
Nimble handles retrieval infrastructure that developers would otherwise have to build themselves, including:
- JavaScript rendering
- Anti-bot and proxy infrastructure
- Page interaction and site navigation
- Search plus full-page extraction
Full research orchestration.
Web Search Agents go beyond retrieval to handle:
- Effort scoping
- Search and extraction orchestration
- Site navigation
- Parsing and JavaScript rendering
- Research synthesis
- Schema and output rules
- Confidence scoring
How to Get Started with Nimble's Search API and Web Search Agents
Search API
Use the Search API when you want your own application or agent to control what happens with the data while Nimble handles reliable web search and retrieval.
Docs: https://docs.nimbleway.com/nimble-sdk/web-tools/search
Web Search Agents
Use Web Search Agents when you want Nimble to automate the research workflow itself, from planning and retrieval through synthesis and structured output.
Docs: https://docs.nimbleway.com/nimble-sdk/web-search-agents/overview
FAQ
Answers to frequently asked questions