

Give Mastra Agents More Complete Web Context with Nimble
Connect Mastra agents to Nimble through the @nimble-way/mastra package or the Nimble MCP Server, and give them complete, cited web data to act on.


Nimble's Expert
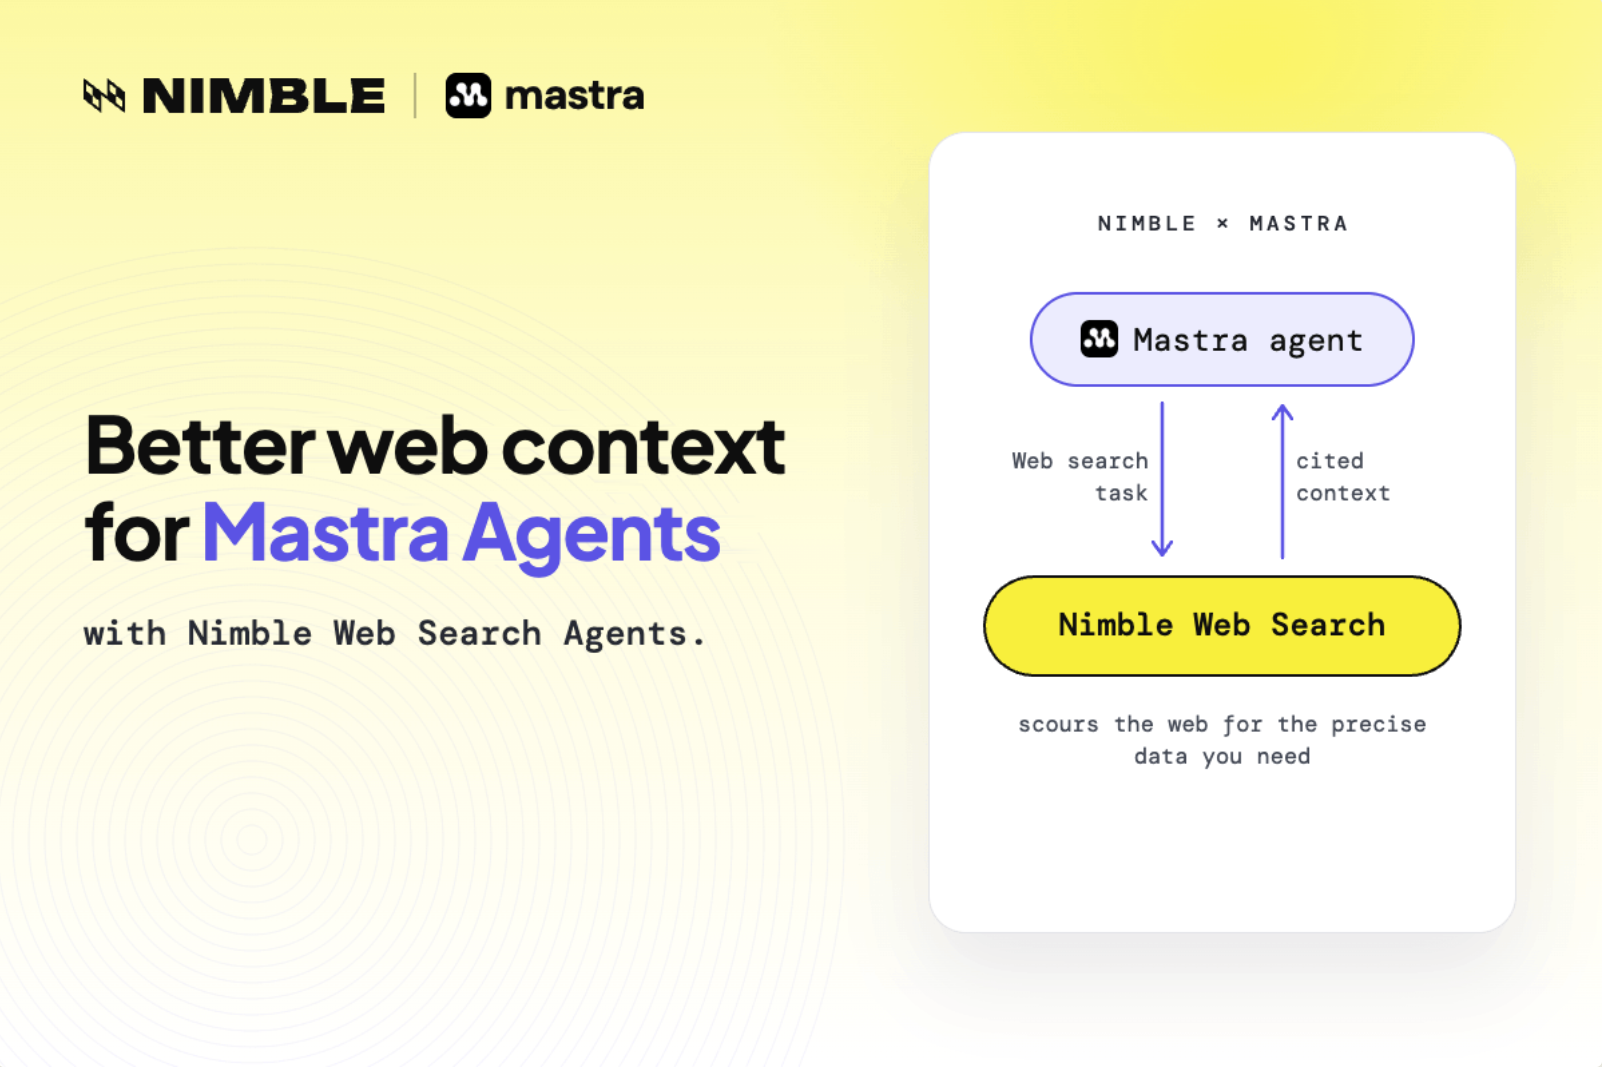
Give Mastra Agents More Complete Web Context with Nimble
Connect Mastra agents to Nimble through the @nimble-way/mastra package or the Nimble MCP Server, and give them complete, cited web data to act on.
Nimble's Expert


Most popular articles
Get structured, reliable data for your stack.
Today, we’re introducing the Nimble integration for Mastra, giving developers a way to equip their agents with deeper web research capabilities. Through the @nimble-way/mastra package or the Nimble MCP Server, Mastra agents can search across sources, extract structured data, and return answers grounded in cited evidence.
What You Can Do with the Nimble Mastra Integration
When Mastra agents search the web, they rely on the LLM’s built-in web search tools by default. These tools are great for basic look ups, but….
Nimble closes those gaps with Web Search Agents. A Web Search Agent plans the research, searches across sources, opens and reads the pages that matter, extracts the fields you asked for, and checks each value against its source. The result comes back as prose or as JSON that matches your schema, with a source and confidence grade behind every claim. It works with any model Mastra supports, including local and open-weight models, because the research runs on Nimble rather than through your model provider.
With the package, developers stay in control of what the agent can do:
- Complete, structured output: Pass an outputSchema and every run returns JSON in the shape your app expects, ready to write to a database or render in a UI.
- Evidence and confidence scoring for every claim: Completed runs include per-claim citations with verbatim excerpts, source URLs, and confidence grades, so your agent and your users can see where each value came from.
- Predictable cost and scope: Set an effortCap so the model can't request more research than you allow, and limit runs to a sources allowlist of domains.
- Context that improves over time: A reused Web Search Agent keeps memory across runs, so recurring research gets faster and up to 50% cheaper.
Cookbook example: Live web research for Mastra agents
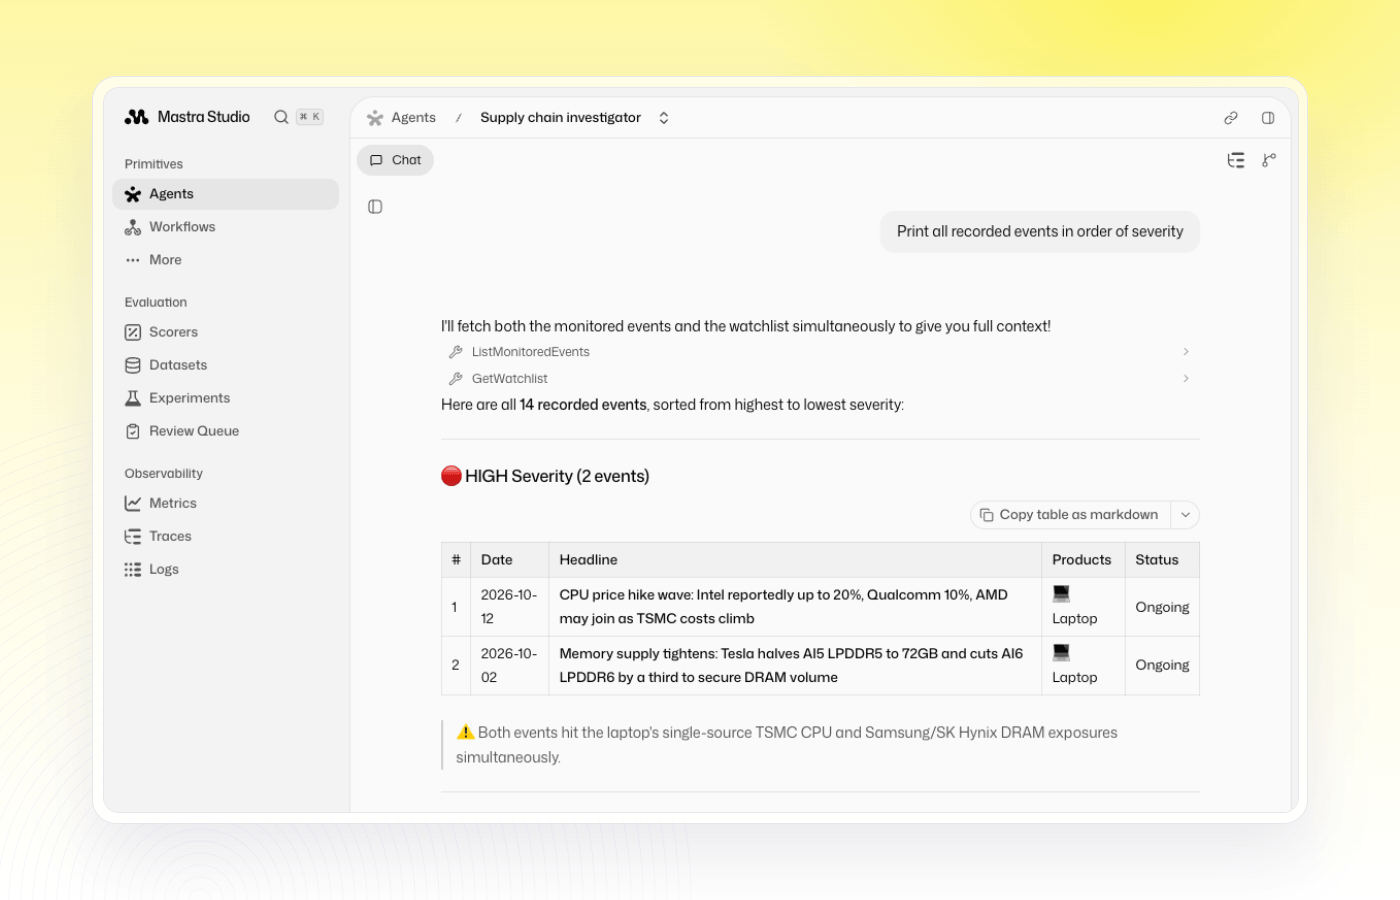
A port strike, an export ban, or a fire at a supplier's plant can hold up a product for weeks. The news usually breaks first in trade press and official notices, days before it shows up in a shipment. The cookbook turns that into a Mastra app: a supply chain monitor that watches three consumer electronics products and researches the live web three times a day for anything that touches their suppliers, materials, or shipping routes.
It's built on the @nimble-way/mastra package, and it uses the tools two ways: from a scheduled workflow, and from a chat agent.
Start research from a workflow step. A Web Search Agent run takes minutes, so the sweep workflow doesn't wait for one. It starts a run per product and stores the runId. The developer sets the output schema, the sources, and the effort once, and code decides when a run starts, not the model:
import { createStep } from "@mastra/core/workflows";
import { nimbleAgentStartRunTool } from "@nimble-way/mastra";
import { z } from "zod";

const startSweep = nimbleAgentStartRunTool({
  agentId: process.env.NIMBLE_SWEEP_AGENT_ID,
  outputSchema: SWEEP_OUTPUT_SCHEMA,
  sources: SWEEP_SOURCES, // trade press, wires, and official notices only
  effort: "high",
});

const startRuns = createStep({
  id: "start-runs",
  inputSchema: z.object({ tasks: z.array(z.string()) }),
  outputSchema: z.object({ runIds: z.array(z.string()) }),
  execute: async ({ inputData }) => {
    const runIds: string[] = [];
    for (const task of inputData.tasks) {
      const run = (await startSweep.execute!({ task }, {} as never)) as { runId: string };
      runIds.push(run.runId);
    }
    return { runIds };
  },
});
Collect it on a later tick. A separate collect workflow runs a few minutes later and asks for each result. A run that's still working comes back with ready: false and waits for the next tick, so the server can sleep in between:
import { nimbleAgentRunResultTool } from "@nimble-way/mastra";

const collectSweep = nimbleAgentRunResultTool({ agentId: process.env.NIMBLE_SWEEP_AGENT_ID });

const result = (await collectSweep.execute!({ runId }, {} as never)) as { ready: boolean };
if (!result.ready) return; // still researching; the next tick picks it up
Read the evidence behind every field. Because the run has an output schema, each value in the answer has its own claim, keyed by its JSON path. Here's the claim behind the status of one event from a live sweep:
{
  "path": "$.events[0].status",
  "confidence": "high",
  "reasoning": "Backed by a primary source (news)",
  "citations": [
    {
      "url": "<https://theloadstar.com/capacity-conundrum-for-shippers-as-carriers-unveil-post-golden-week-blanks>",
      "source_type": "primary",
      "source_category": "news"
    }
  ]
}
The monitor uses those grades to decide what reaches people. A serious event whose key facts are well sourced goes to Slack with its sources. If any key fact rests on a low-confidence claim, the event goes into the daily digest as unconfirmed instead.
Give the same tools to a chat agent. In Mastra Studio, an investigator agent answers questions about what the monitor found. When a question needs fresh research, it starts a deep dive with createNimbleAgentTools({ effortCap: "high" }), reports the runId, and collects the cited briefing in a later turn. The effort cap means the model can't request more research than the developer allows.
The repo includes recorded results from live sweeps, so the full flow of sweep, collect, alert, and digest runs on your machine with no API keys. Explore the cookbook here.
Run Web Search Agents on the live web. Get structured, reliable data for your stack. Start building.
FAQ
Answers to frequently asked questions