

Developer guide: Building social listening agents with Nimble (+ examples)
Three social listening workflows, each built two ways on a real Gymshark campaign: with the Search API and with Web Search Agents.


Charlie Klein
Developer guide: Building social listening agents with Nimble (+ examples)
Three social listening workflows, each built two ways on a real Gymshark campaign: with the Search API and with Web Search Agents.
Charlie Klein
TL;DR
- What this guide covers: three social listening workflows built with Nimble, using Gymshark's October 2026 "Megan Does Gym" campaign as the running example: (1) campaign reaction, (2) creator discovery and vetting, (3) competitor benchmarking against Alo Yoga, Lululemon and AYBL. Each has a runnable cookbook app: social-campaign-reaction, social-creator-discovery, social-competitor-benchmark.
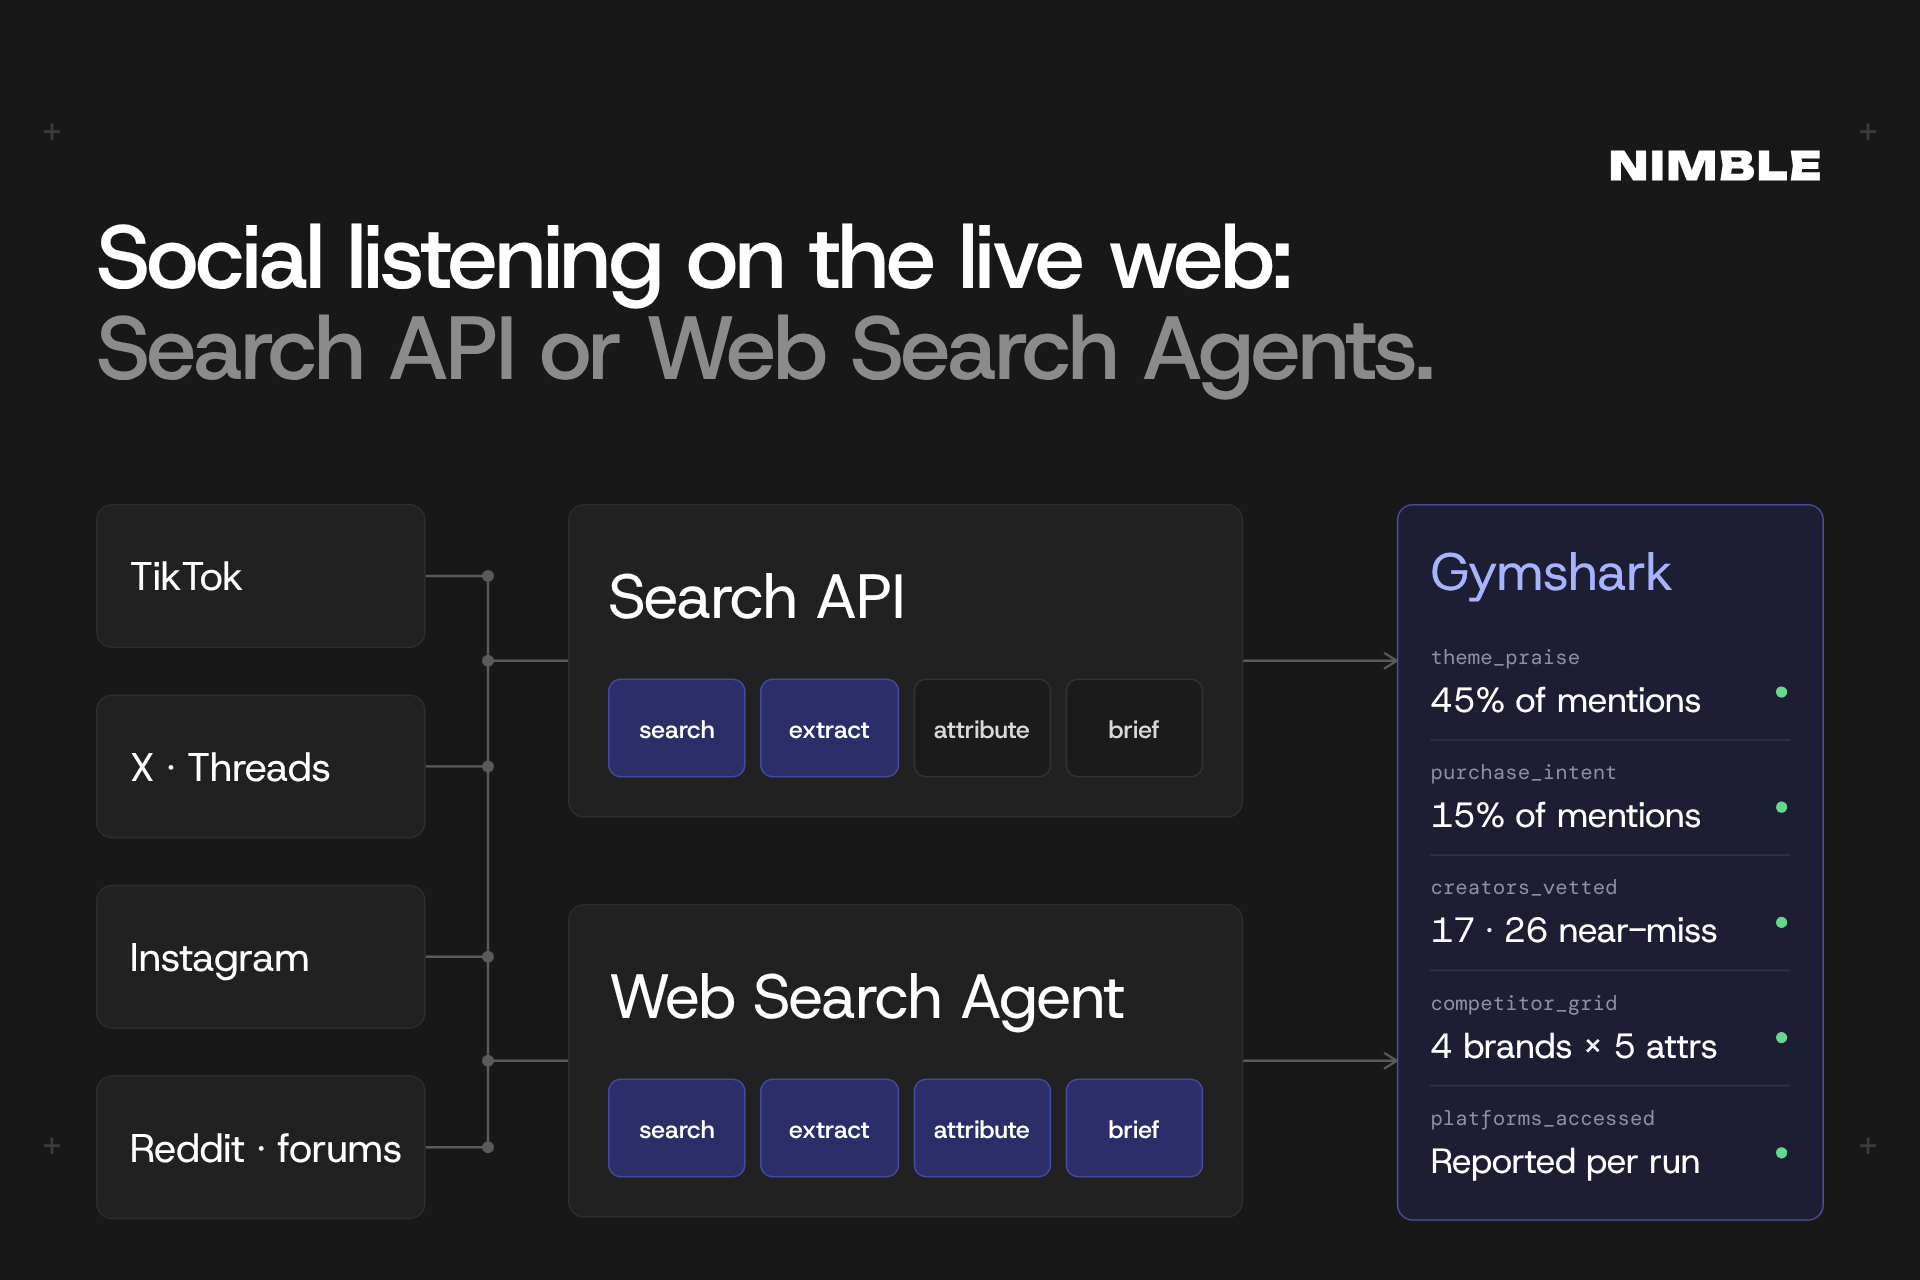
- Two implementations per workflow: Search API + Extract Templates (your code chooses the platforms, collects posts and profiles, and does the counting), or Web Search Agents (you describe the task, the constraints and the JSON you want back, and Nimble plans and runs the research).
- Social data is platform-shaped. The Search API with
include_domainsset to one platform returns TikTok engagement counts, X and Threads post text, Instagram post IDs, and full Reddit comment threads (search_depth="standard"). - Extract Templates turn a handle or post ID into exact fields.
tiktok_accountreturns follower count, bio and dated recent posts;instagram_postreturns caption, likes and recent comments. - Web Search Agents cover forums, review sites and cross-platform synthesis, and return a per-platform coverage report (
platforms_accessed) with every run. - Neither path saw everything. In each use case below, the searches and the Agent turned up evidence the other did not, so the real decision is which parts of the workflow your code should own. Date filters and quote checks belong in code either way.
- Which to choose: the Search API path when numbers have to be defensible, since every share and verdict traces to IDs your code counted; the Agent when a finished brief, list or grid is the goal and forum and review coverage matters. They combine well: run the Agent for breadth, then re-check its results with the same Extract Templates.
On October 13, 2026, Gymshark announced Megan Thee Stallion as its first celebrity ambassador. Over the next eight days, the campaign video on her TikTok collected 253.3K likes and 1,817 comments. Fan accounts on X said the collection was "selling out already". A post on Threads said the timing rubbed people the wrong way, coming right after Gymshark was criticized for not recognizing Crannon, a Black world champion. A fitness coach with 34.4K followers posted a review asking whether the collab was tone-deaf.
A brand team reading that week needs all of it, and each platform returns it in a different shape. TikTok search snippets carry like and comment counts. X and Threads results carry the post text. Instagram comments sit on the post page. Reddit threads carry the comments but no dates.
The sections below build three social listening workflows on that data, from Gymshark's side: reading the reaction to the campaign, finding creators to sign next, and benchmarking against Alo Yoga, Lululemon and AYBL. Each workflow has two implementations:
- Search API and Extract Templates: your code chooses the platforms, collects posts and profiles, and does the counting.
- Web Search Agents: you describe the task, the constraints and the JSON you want back, and Nimble plans and runs the research.
Use Case 1: Campaign Reaction
A week after a launch, the brand team wants a read on the reaction: what people like, what they object to, how big each camp is, and links to the posts so someone can check.
Sampling one platform gets that read wrong. In this campaign, buying intent showed up on X, the sharpest criticism in a TikTok creator review and a Threads post, and the longest conversation on a forum.
The target here is "Megan Does Gym", read over October 1-21, 2026. The reaction split early, which makes it a good stress test: the campaign video passed 250K likes in the same week as the Threads backlash post and the "tone-deaf" review.
Want to run the below examples yourself? Both are available here: social-campaign-reaction
Search API: when you need to count the mentions yourself
To say a theme is 20% of the conversation, you need to know what the 100% is. When your code picks the platforms and decides what counts as a mention, it has that total and computes every share itself instead of trusting an estimate.
The pipeline runs a separate search for each platform, so every result list comes back in a single, predictable format.
The request:
from nimble_python import Nimble

nimble = Nimble()

searches = [
    {"query": "Gymshark Megan Thee Stallion", "include_domains": ["tiktok.com"],
     "search_depth": "lite", "max_results": 15},
    {"query": "Gymshark Megan Thee Stallion", "include_domains": ["x.com", "threads.com", "threads.net"],
     "search_depth": "lite", "max_results": 15},
    {"query": "Gymshark instagram post Megan Does Gym", "include_domains": ["instagram.com"],
     "search_depth": "lite", "max_results": 10},
    {"query": "Gymshark", "include_domains": ["reddit.com"],
     "search_depth": "lite", "time_range": "month", "max_results": 20},
]

results = {s["include_domains"][0]: nimble.search(**s).results for s in searches}
Among the results:
[
  {
    "title": "Thee newest Gymshark athlete. Megan Does Gym. #ad  | TikTok",
    "url": "https://www.tiktok.com/@theestallion/video/7696213996071963917",
    "description": "253.3K Likes, 1817 Comments. TikTok video from Megan Thee Stallion (@theestallion): “Thee newest Gymshark athlete. Megan Does Gym. #ad”. shane gillis. original sound - Megan Thee Stallion."
  },
  {
    "title": "Gymshark x Megan Thee Stallion review: Was the collab tone- ...",
    "url": "https://www.tiktok.com/@crunchedbycait/video/7696655938857569549",
    "description": "Caitlin 💗 · crunchedbycait · 446Following · 34.4KFollowers · 1.1MLikes · Online Fitness & Nutrition Coach 💖 JOIN MY COMMUNITY! ⬇️ · linktr.ee/crunchedbycait · Log in"
  },
  {
    "url": "https://www.threads.com/@sincerelyyours_ki/post/DehaQvXEXSv/girl-gymshark-caught-backlash-after-people-called-them-out-for-not-giving/",
    "description": "Girl, Gymshark caught backlash after people called them out for not giving Crannon, a Black world champion, the recognition they felt she deserved. Then they announced a campaign with Megan Thee Stallion, and the timing rubbed a lot of people ..."
  }
]
TikTok returned the numbers and the sharpest criticism. Threads returned the backlash. Instagram returned post URLs, and the comments sit behind them. Their shortcodes go to the instagram_post Extract Template, which returns the post and its recent comments:
import re

post_ids = re.findall(r"instagram\.com/(?:p|reel)/([A-Za-z0-9_-]{6,})",
                      " ".join(r.url for r in results["instagram.com"]))

post = nimble.extract.templates.run(template="instagram_post", params={"post_id": "DegDM4CjGgh"})
Among the results (data.parsing):
{
  "url": "https://www.instagram.com/p/DegDM4CjGgh",
  "date_posted": "2026-10-15T05:00:03.000000Z",
  "content_type": "Carousel",
  "likes": 25233,
  "num_comments": 203,
  "latest_comments": [
    {"comment": "No wonder her work out on NTC is no longer available"},
    {"comment": "She looks so good she looks like a video game character omg"},
    {"comment": "Free tory lanez"}
  ]
}
Parameters used:
include_domainsset to one platform per search.search_depth="lite": titles and snippets are enough for TikTok counts, X post text and Instagram post URLs.time_range="month"on Reddit, which has no dates in its results.instagram_postwithpost_id: about 3 seconds per post, up to 15 recent comments.
Those three comments show why the next step is an LLM, not a keyword count. One is on-topic praise, one notes her workout is no longer on NTC (Nike Training Club), and one is about an unrelated court case.
The agent passes every post and comment to Claude, which returns themes with the IDs of the posts that express them. Code computes each theme's share from those IDs, drops any quote not found in the post it cites, and removes quotes dated before the window. Every share in the output can be recomputed from the stored IDs, and every quote points back to the post it came from.
Agent API: when you want the finished brief
The Agent version replaces the per-platform searches, the comment fetches and the Claude step with one call.
The request:
run = nimble.agents.run(
    agent_name="social-campaign-reaction",
    use_case="research",
    effort="high",
    input=(
        "Analyze consumer sentiment toward Gymshark from 2026-10-01 to today, with focus on "
        "reactions to the Megan Thee Stallion ambassador campaign (\"Megan Does Gym\", announced "
        "~Oct 14 2026) and Gymshark products in general. Use social and community sources: Reddit "
        "threads and comments, TikTok videos and comments, Instagram posts and comments, YouTube "
        "videos and comments, X/Threads posts, and review sites (Trustpilot etc). Group what people "
        "say into themes (praise and complaints), estimate each theme's share of the mentions you "
        "found, and quote real posts or comments verbatim with their platform, date, engagement "
        "(upvotes/likes/views if visible) and URL. Report which platforms you could and could not "
        "access. Do not invent quotes; only include text you actually read."
    ),
    output_schema=REACTION_SCHEMA,
)
Parameters used:
use_case="research"andeffort="high": open-ended gathering and synthesis across sources. The run took 7 minutes 53 seconds.input: the window, the campaign, the sources to try, and two rules: quote only text the Agent read, and report which platforms it accessed.output_schema:overall_summary,platforms_accessed(platform,accessed,items_read,note) andthemes(theme,polarity,share_of_mentions,platforms, andquoteswithtext,platform,date,engagement,url).
Among the results:
{
  "themes": [
    {
      "theme": "Praise for Megan Thee Stallion and the 'Megan Does Gym' campaign (appearance, aura, styling, brand evolution)",
      "polarity": "positive",
      "share_of_mentions": "≈45% of the ~75 individual social mentions read — the dominant theme",
      "quotes": [
        {"text": "She looks so great and FIT!", "platform": "Lipstick Alley", "date": "2026-10-14", "engagement": "7 Thanks",
         "url": "https://www.lipstickalley.com/threads/megan-thee-stallion-for-gymshark.6206349/"}
      ]
    },
    {
      "theme": "Brand-relevance and celebrity-fit debate (is Gymshark still relevant, does a celebrity ambassador fit the brand, styling critiques)",
      "polarity": "mixed",
      "share_of_mentions": "≈10% of the ~75 social mentions read",
      "quotes": [
        {"text": "I didn't realize Gymshark was still around.", "platform": "Lipstick Alley", "date": "2026-10-14", "engagement": "6 Thanks",
         "url": "https://www.lipstickalley.com/threads/megan-thee-stallion-for-gymshark.6206349/"}
      ]
    }
  ],
  "platforms_accessed": [
    {"platform": "Lipstick Alley (forum)", "accessed": true, "items_read": 29},
    {"platform": "Trustpilot", "accessed": true, "items_read": 8,
     "note": "Profile stats (3.5/5, 42,308 reviews) plus the most-recent reviews, including three dated Oct 12, 2026 with full text and Useful counts; ..."}
  ]
}
The full brief has six themes: praise (about 45%), purchase intent (15%), "the campaign made me want to work out" (12%), brand relevance (10%), product and service complaints from October Trustpilot reviews (10%), and hostile comments about Megan's body (8%). Every quote carries a platform, date and engagement count, and every claim carries a confidence grade and citations (201 claims: 139 high, 26 medium, 36 low). Negative themes can go straight to the comms team, and a daily re-run turns the shares into a trend line.
The two approaches read different parts of the reaction:
The Agent's brief reads mostly positive because its sources were Reddit, a forum, X post pages and review sites. The sharpest criticism was on TikTok and Threads, which the searches covered. The 29-post forum thread and the review sites appear only in the Agent's brief. A brand team reading only one of them would get a different story.
Choose the Search API path when the numbers have to be defensible, since every share traces to IDs your code counted. Choose the Agent when a finished brief is the goal and forum and review coverage matters; its platforms_accessed report shows which platforms the brief covers.
Use Case 2: Creator Discovery and Vetting
Megan was a celebrity signing. This use case covers the other end of the roster: coaches and lifters with 10K to 500K followers who post every week.
The influencer team writes a brief, and the partnerships manager needs a shortlist they can email: verified follower counts, a recent post, a location, and any conflicting deal surfaced before the first call.
Creators don't describe themselves in those terms. A search snippet says "34.4KFollowers". A bio says "2M on YouTube" next to a 115K TikTok account. A deal with a competitor appears as "dc NEENY" in a caption.
The brief used here:
- US-based
- 10,000-500,000 followers on the main platform
- Women's strength training, lifting, gym fits or activewear reviews
- Posted within the last 30 days
- Not already a Gymshark athlete; deals with Alo, Lululemon, AYBL, Oner Active, DFYNE, Nike, Buffbunny or Alphalete flagged with evidence
Want to run the below examples yourself? Both are available here: social-creator-discovery
Search API: when you need to vet each creator yourself
Search finds candidate creators, and the tiktok_account Extract Template pulls each one's profile: the exact follower count, the bio, and dated recent posts. Your code then checks every creator against the brief and decides who stays on the list.
The request:
import re

lead_searches = [
    {"query": "AYBL vs Gymshark leggings honest review", "include_domains": ["tiktok.com"],
     "search_depth": "lite", "max_results": 15},
    {"query": "Gymshark try on haul honest review", "include_domains": ["tiktok.com"],
     "search_depth": "lite", "max_results": 15, "time_range": "month"},
    # ... 11 searches across TikTok, Instagram and YouTube
]

handles = {
    h.lower()
    for s in lead_searches
    for r in nimble.search(**s).results
    for h in re.findall(r"tiktok\.com/@([A-Za-z0-9._]{2,30})/video/", r.url)
}

profile = nimble.extract.templates.run(template="tiktok_account", params={"account_id": "dailyjlh"})
Among the results, a single-video search result with the creator's handle in the URL:
{
  "title": "AYBL Leggings Comparison Ahead of Birthday Sale",
  "url": "https://www.tiktok.com/@dailyjlh/video/7483241383147474198",
  "description": "3217 Likes, 120 Comments. TikTok video from neeny (@dailyjlh): “Comparing all the collections of leggings from @AYBL before their Birthday Sale starts (Monday 24th March 7pm - up to 60% off and even more savings with my code NEENY) ..."
}
And that handle's profile from tiktok_account (data.parsing):
{
  "account_id": "dailyjlh",
  "nickname": "neeny",
  "followers": 337900,
  "videos_count": 2232,
  "biography": "@AYBL & @GHOST LIFESTYLE athlete 👻\ndiscount code NEENY",
  "top_videos": [
    {"create_date": "2026-10-21T06:50:44.000000Z", "playcount": 1702,
     "description": "nothing better than that 🤭 #gym #gymtok #rdl #personalbest "},
    {"create_date": "2026-10-20T16:08:06.000000Z", "playcount": 5264,
     "description": "big biceps for MEEEEE 👹🤭 @AYBL dc NEENY (enhance collection new colours coming soon) #gym #gymtok #bicepcurls #gymhack"}
  ]
}
Parameters used:
- 11 lite searches, each limited to TikTok, Instagram or YouTube.
- Handles come from single-video TikTok URLs (
tiktok.com/@handle/video/...), whichtiktok_accounttakes directly. Caption @mentions are skipped; many are brands or display names. tiktok_accountwithaccount_id: 40-48 seconds per profile.
The gates are code: follower count in range, a post dated within 30 days, no audience above the cap stated in the bio, and no Gymshark code or athlete tag. A brand name next to "athlete", "code" or "dc" in the bio or captions marks a competitor deal. Claude reads the bio and captions of each creator who passes and returns us_based, content_fit and own_brand.
The 11 searches produced four handles, and two passed the gates. Both are creators a partnerships team needs to know about before reaching out. @dailyjlh (337,900 followers) carries AYBL codes in her bio and in a post from the day before the run. @crunchedbycait, the Atlanta-based coach behind the "tone-deaf" review in Use Case 1, launched her own brand, Crunched Athletics, on October 15.
Agent API: when you want the vetted list
The Agent version takes the same brief as hard criteria and finds the creators itself.
The request:
run = nimble.agents.run(
    agent_name="social-creator-discovery",
    use_case="dataset_building",
    effort="high",
    input=(
        "Find up to 20 US-based fitness creators that Gymshark (gymshark.com) could recruit for its "
        "women's training line. Criteria: 10,000-500,000 followers on their main platform (TikTok, "
        "Instagram or YouTube); content focused on women's strength training, lifting, gym fits or "
        "activewear reviews; posted on that platform within the last 30 days (today is 2026-10-21); "
        "NOT currently a Gymshark athlete or ambassador. For each creator, check for current or "
        "recent (2025-2026) brand partnerships, especially with competitors Alo, Lululemon, AYBL, "
        "Oner Active, DFYNE, Nike, Buffbunny, Alphalete, and record them with evidence. List "
        "near-misses (e.g., already a Gymshark athlete, over 500K followers, not US-based, inactive) "
        "with the criterion they failed. Only include creators whose follower count and recent "
        "activity you verified from a cited page; never pad the list."
    ),
    output_schema=CREATOR_SCHEMA,
)
Parameters used:
use_case="dataset_building": builds a list of entities that match criteria. It requireseffort="high"or above. The run took 15 minutes 11 seconds.input: the brief as hard constraints, a cap of 20, a request for near-misses, and "never pad the list".output_schema: acreatorslist (handle,main_platform,followers,followers_source_url,location,last_post_date,current_brand_partners,competitor_conflict,partnership_evidence_urls,why_fit) and anear_misseslist (handle,failed_criterion,reason).
Among the results:
{
  "creators": [
    {
      "handle": "@_brittanylupton",
      "main_platform": "Instagram",
      "followers": "424K",
      "location": "Florida, US (bio: '📍 FL')",
      "last_post_date": "2026-10-19",
      "current_brand_partners": ["Oner Active (@oneractive BRITTANY)", "Runna (@runna BRITTANY)"],
      "competitor_conflict": true
    },
    {
      "handle": "@maddiliftss",
      "main_platform": "TikTok",
      "followers": "23.5K",
      "location": "United States",
      "last_post_date": "2026-10-20",
      "current_brand_partners": [],
      "competitor_conflict": false
    }
  ],
  "near_misses": [
    {
      "handle": "@whitneyysimmons",
      "failed_criterion": "Not currently a Gymshark athlete; 10K-500K followers",
      "reason": "Already a Gymshark athlete — Gymshark sells dedicated 'Whitney Simmons' and 'Adapt X Whitney' collections; also ~4M followers, over the 500K cap."
    },
    {
      "handle": "@kassgfit",
      "failed_criterion": "US-based",
      "reason": "266K Instagram followers and active (Oct 19, 2026), but her Threads profile is location-tagged Vancouver, British Columbia — not US-based."
    }
  ]
}
The Agent returned 17 creators (9 on Instagram, 8 on TikTok, 23.5K to 488K followers) and 26 near-misses. Two creators were flagged for Oner Active deals. Fourteen near-misses failed the 30-day activity check.
The near-misses are as useful as the list: @whitneyysimmons is already a Gymshark athlete, and @kassgfit is based in Vancouver. Each creator also carries a followers_source_url and partnership evidence URLs, so a reviewer can open the page behind any number.
Checking the Agent's list with the same template
Follower counts decide who makes the shortlist, so they are worth checking. The tiktok_account template that gates the Search API path can re-check the Agent's TikTok creators:
for creator in run_result["creators"]:
    if creator["main_platform"] == "TikTok":
        profile = nimble.extract.templates.run(
            template="tiktok_account", params={"account_id": creator["handle"].lstrip("@")}
        )
Three checks confirmed all three follower counts and recent posts. One bio changed the verdict:
{
  "account_id": "vickyjustiz",
  "followers": 115000,
  "biography": "hot and cool mom in Miami 🌴\nfounder + fitness coach ➡️ @dailythrive \n2M on YouTube 🏆 💪🏼"
}
The Agent qualified her on 115K TikTok followers. Her bio states 2M on YouTube, four times the cap. A regex on the bio catches it; the cookbook's --verify mode runs the check.
The two lists don't overlap. The Agent found 17 creators across Instagram and TikTok and explained every rejection. Search and the template surfaced @dailyjlh and @crunchedbycait, neither of them in the Agent's 17, and caught the creator whose real reach was on another platform.
In practice the two combine well: run the Agent for breadth, then put every TikTok creator it returns through the same tiktok_account checks the Search API path uses.
Use Case 3: Competitor Benchmarking
The first two use cases look at Gymshark's own campaign and roster. Shoppers don't judge it alone, though. They compare it with Alo Yoga, Lululemon and AYBL, often in the same sentence.
A merchandising team wants that comparison as a grid: four brands by five attributes (fit and sizing, fabric quality, price and value, style, customer service), each cell with a verdict and the quotes behind it, plus a list of who switched brands and why. Only opinions posted since 2025-01-01 count.
"I love a few pieces from Alo but overall I find Lulu’s quality to be better" is one comment holding two opinions, one per brand. Most comments like it are on Reddit, where search results carry no dates.
Want to run the below examples yourself? Both are available here: social-competitor-benchmark
Search API: when you need to trace every verdict to a comment
Search pulls Reddit threads with their comments (search_depth="standard"), plus TikTok and X/Threads snippets. Your code then decides which opinions count, which brand each one belongs to, and where a cell tips from mixed to strength.
The request:
reddit = {"include_domains": ["reddit.com"], "search_depth": "standard", "max_results": 4}

searches = [
    {"query": "Gymshark vs Lululemon leggings", **reddit},
    {"query": "Alo vs Lululemon quality", **reddit},
    {"query": "AYBL vs Gymshark", **reddit},
    {"query": "switched from Lululemon to Alo Gymshark", **reddit},
    {"query": "Alo yoga worth the price", **reddit},
    {"query": "Gymshark sizing inconsistent", **reddit},
    {"query": "Gymshark vs Alo vs Lululemon honest review", "include_domains": ["tiktok.com"],
     "search_depth": "lite", "max_results": 15},
    {"query": "AYBL vs Gymshark", "include_domains": ["tiktok.com"], "search_depth": "lite", "max_results": 15},
    {"query": "lululemon vs alo vs gymshark", "include_domains": ["x.com", "threads.com"],
     "search_depth": "lite", "max_results": 15},
]
Among the results (comment text truncated, usernames redacted):
{
  "title": "r/Activewear on Reddit: Switching from Lulu to Alo Yoga???",
  "url": "https://www.reddit.com/r/Activewear/comments/1keoi9v/switching_from_lulu_to_alo_yoga/",
  "description": "# Switching from Lulu to Alo Yoga???\n## [user]\nI’m a lulu girlie and have tried a few things from alo and it’s just ok I also haven’t been impressed by alo’s quality for the most part ... ### [user]\nAlo quality has gonna down hill in the last couple years as the price goes up for sure, I’d stick with Lulu ## [user]\nI love a few pieces from Alo but overall I find Lulu’s quality to be better and more functional (and cheaper). ..."
}
The nine searches returned 69 results: 24 Reddit results covering 22 unique threads with 622 comments, plus 45 TikTok and X/Threads snippets. 264 of the 667 units name two or more brands.
Two problems sit in that text.
Age. Reddit results carry no date. Thread IDs are base-36 counters that grow over time, so the code dates each thread from its ID against threads of known date:
ANCHORS = [("1iilkp4", date(2025, 2, 5)), ("1keoi9v", date(2025, 5, 4)), ("1x55i68", date(2026, 10, 13))]

def reddit_thread_date(url: str) -> date:
    n = int(re.search(r"/comments/([a-z0-9]+)", url)[1], 36)
    pts = [(int(i, 36), d) for i, d in ANCHORS]
    (lo_n, lo_d), (hi_n, hi_d) = (pts[0], pts[1]) if n < pts[1][0] else (pts[1], pts[2])
    per_day = (hi_n - lo_n) / (hi_d - lo_d).days
    return lo_d + timedelta(days=round((n - lo_n) / per_day))
13 of the 22 threads date before 2025 and are dropped, which leaves 150 comments that name a brand.
Attribution. Counting sentiment keywords per comment scored Alo Yoga's quality as mostly positive: 128 mentions, 56 positive, 27 negative. A comment like "I love a few pieces from Alo but overall I find Lulu’s quality to be better" carries positive words, and a per-comment score credits them to every brand it names, Alo included. Restricted to comments that name one brand, Alo quality splits 12 positive and 14 negative.
So Claude attributes each opinion to one brand and one attribute, with the quote that supports it:
class Opinion(BaseModel):
    unit_id: int
    brand: Literal["Gymshark", "Alo Yoga", "Lululemon", "AYBL"]
    attribute: Literal["fit & sizing consistency", "fabric quality & durability", "price/value",
                       "style & design", "customer service (shipping, returns, support)"]
    polarity: Literal["positive", "negative", "mixed"]
    quote: str  # shortest verbatim span of the comment that states the opinion
Parameters used:
search_depth="standard"on Reddit: the thread text with its comments, often more than 40 per thread.search_depth="lite"on TikTok and X/Threads: snippets, mostly TikTok topic pages that mix several creators' captions.- Code sets each cell's verdict from the attributed opinions:
strengthwhen (positive − negative) / total ≥ 0.35,weaknessat ≤ −0.35, otherwisemixed; fewer than 4 opinions ismixedand flagged.
Each verdict can be rebuilt from its attributed opinions, and each opinion from a dated comment.
Agent API: when you want the finished comparison
The Agent returns the same grid: one row per brand and attribute, with each quote in its own column. The rows are flat because output schemas allow at most five levels of nesting, and every object and array counts as a level. A list of brands, each holding a list of attributes, each holding a list of quotes, goes deeper than that.
The request:
run = nimble.agents.run(
    agent_name="social-competitor-benchmark",
    use_case="research",
    effort="high",
    input=(
        "Benchmark consumer opinion of four women's activewear brands: Gymshark (gymshark.com), "
        "Alo Yoga (aloyoga.com), Lululemon (lululemon.com) and AYBL (aybl.com). Compare them on "
        "five attributes: fit & sizing consistency, fabric quality & durability, price/value, "
        "style & design, and customer service (shipping, returns, support). Use consumer voices "
        "only: Reddit threads and comments, forums, TikTok/YouTube review content, X/Threads, and "
        "review sites (Trustpilot, etc.). Prioritize posts from 2025-2026 and especially head-to-head "
        "comparisons where a consumer compares two or more of these brands. Exclude discussion of "
        "marketing campaigns or celebrity ambassadors. Return one row per brand x attribute (20 rows) "
        "with a verdict (strength / mixed / weakness), a one-line summary of what consumers say, and "
        "up to 2 verbatim quotes with platform, date and URL. Also list head-to-head comparisons you "
        "found (who switched from which brand to which and why). Report which platforms you could "
        "and could not access. Never invent quotes; only include text you actually read."
    ),
    output_schema={
        "type": "object",
        "properties": {
            "cells": {"type": "array", "items": {"type": "object", "properties": {
                "brand": {"type": "string"}, "attribute": {"type": "string"},
                "verdict": {"type": "string"}, "summary": {"type": "string"},
                "quote_1": {"type": ["string", "null"]}, "quote_1_date": {"type": ["string", "null"]},
                "quote_1_url": {"type": ["string", "null"]},
                # ... quote_1_platform, quote_2, quote_2_platform, quote_2_date, quote_2_url
            }}},
            "head_to_head": {"type": "array", "items": {"type": "object", "properties": {
                "from_brand": {"type": "string"}, "to_brand": {"type": "string"},
                "reason": {"type": "string"}, "quote": {"type": "string"},
                "platform": {"type": "string"}, "date": {"type": ["string", "null"]}, "url": {"type": "string"},
            }}},
            # ... platforms_accessed
        },
        "required": ["cells", "head_to_head"],
    },
)
Parameters used:
use_case="research"andeffort="high". The run took 9 minutes 54 seconds.input: four brands, five attributes, consumer sources only, 2025-2026 first, no campaign talk, and a request for brand switches.output_schema: flatcellsrows,head_to_headswitches, andplatforms_accessed.
Among the results:
{
  "cells": [
    {
      "brand": "Alo Yoga",
      "attribute": "fabric quality & durability",
      "verdict": "weakness",
      "quote_1": "I own some alo stuff, and the quality is horrible they've all pilled after two or three uses. Imo, pretty much every other brand at that price point has better quality fabrics, and it's just not worth it.",
      "quote_1_date": "May 5, 2025",
      "quote_1_url": "https://www.reddit.com/r/Activewear/comments/1keoi9v/switching_from_lulu_to_alo_yoga/"
    },
    {
      "brand": "Gymshark",
      "attribute": "customer service (shipping, returns, support)",
      "verdict": "strength",
      "quote_1": "Amazing customer service! I contacted customer service with a fault with one of my items and they immediately sent me a replacement. Thank you so much!",
      "quote_1_date": "October 19, 2026",
      "quote_1_url": "https://www.trustpilot.com/reviews/6ad67a93776602f3f4a2f181"
    }
  ],
  "head_to_head": [
    {
      "from_brand": "Alo Yoga",
      "to_brand": "Lululemon",
      "reason": "Alo quality cheap-feeling, airlift leggings like plastic",
      "quote": "I’m an alo girl and switching to lulu. I bought a pair of lulu leggings and I’m hooked. Alo quality just sucks and is not comparable to lulu tbh. Material feels cheap and their airlift leggings are basically plastic",
      "date": "May 8, 2025",
      "url": "https://www.reddit.com/r/Activewear/comments/1keoi9v/switching_from_lulu_to_alo_yoga/"
    }
  ]
}
The full table:
The input asks the Agent to prioritize 2025-2026 posts. Prioritizing is not filtering, so the cookbook's post_process() drops anything dated before MIN_DATE from either path. On this result it reported (excerpt):
{
  "min_date": "2025-01-01",
  "old_quotes_dropped": [
    {"brand": "Gymshark", "attribute": "price/value", "date": "June 8, 2020"},
    {"brand": "Lululemon", "attribute": "customer service (shipping, returns, support)", "date": "October 16, 2020"}
  ],
  "old_switches_dropped": [
    {"from": "Gymshark", "to": "Lululemon", "date": "June 9, 2020"},
    {"from": "Gymshark", "to": "Oner Active", "date": "December 19, 2024"}
  ]
}
In total, 6 quotes and 3 brand switches dated 2020-2024 were dropped, leaving 9 switches. Because every remaining quote has a date and URL, a monthly re-run can diff the grid and flag any cell whose verdict changed.
Coverage split again. The searches returned a Threads exchange from April 2026, "Lulu quality is better. Alo designs are better but quality is crap.", answered by "everything I buy from lulu unravels and all my stuff from Alo is still in tact". The Agent read Trustpilot, whose reviews carried Gymshark's customer-service strength: instant replacements for faulty items in reviews dated October 19, 2026.
For Gymshark, the result reads: service is the advantage, quality decline is the threat, and AYBL competes on value while some shoppers come back for shipping and support ("I'd advise to just stick to Gymshark", r/Gymshark, November 2025).
Across the three use cases, retrieving posts was the easy part. The work was counting them, dating them, attributing each opinion to the right brand, and knowing what each source covered. The Search API path does that in code you can audit. The Agent reaches forums and review sites nobody listed in advance, and reports which platforms it read. Running both behind the same date filter and quote check closed the gaps in every use case here.
Why Nimble Goes Deeper for Social Listening
Search that respects platform boundaries.
A TikTok result, a Reddit thread and an Instagram post each need their own parser. include_domains keeps every result list to one platform: in Use Case 1, four platform-limited searches returned TikTok engagement counts, X and Threads post text, Instagram post IDs, and Reddit thread titles, each in a shape code can parse.
Full comment threads, not snippets.
The opinion is rarely in the post title. search_depth="standard" returned Reddit threads with more than 40 comments each; Use Case 3's 622 comments came from 22 threads and 6 searches.
Exact fields from Extract Templates.
A follower count decides whether a creator makes the shortlist, so it has to be exact. tiktok_account returned exact follower counts, bios and dated posts in about 40 seconds per profile. That made the activity gate and the competitor-deal check deterministic, and it caught the "2M on YouTube" creator the Agent qualified.
Research that reaches forums and review sites.
Some of the most detailed reaction never reaches the major platforms. The Web Search Agents read a 29-post Lipstick Alley thread with reaction counts, dated Trustpilot reviews, and Reddit comments, and returned them in the requested schema. In Use Case 3 that added the customer-service evidence behind Gymshark's one clear strength.
A coverage report with every run.
Every Agent run returned platforms_accessed, with the items read and a note per platform. A pipeline can use it to decide which platforms to cover with platform-limited searches.
Structured output with claim-level trust.
The three outputs here, a themed brief, a vetted creator list and a brand-by-attribute grid, are all JSON in a schema you define. Each Agent run also returned a trust block: 201 graded claims in Use Case 1, 298 in Use Case 2, 351 in Use Case 3. A pipeline can route low-confidence claims to a check like the tiktok_account re-verification above.
How to Get Started with Nimble’s Search API and Web Search Agents
Start with a free trial to get an API key.
The quickest way to try Nimble is the three cookbook apps behind this post. Each one runs both paths with python agent.py and includes the Agent results shown above as examples:
- social-campaign-reaction: campaign reaction across TikTok, X/Threads, Instagram and Reddit.
- social-creator-discovery: creator discovery and vetting with
tiktok_account. - social-competitor-benchmark: brand-by-attribute benchmarking from Reddit, TikTok, X/Threads and review sites.
Each app includes an ai-setup.md, so an AI coding assistant can set it up for you.
To test Nimble on your own use case, start with your own AI assistant. Give it this link to get set up.
To embed Nimble into your social listening workflows:
- Explore Nimble’s integrations with LangChain, LlamaIndex, LiteLLM, and other AI frameworks.
- Install the Nimble SDK for your preferred language.
- Or connect through the Nimble MCP Server.
FAQ
Answers to frequently asked questions